Every blueprint ships with source code, sample data, and step-by-step instructions — ready to run on your Cloudera Platform
-
Blueprint Card
Overview
Build confidence in enterprise AI with standardized model testing, agent evaluation, and transparent performance insights on Cloudera.
As organizations introduce new AI models and autonomous agents, determining whether these systems are accurate, reliable, and suitable for business-critical applications becomes increasingly challenging. Without consistent evaluation processes, teams risk deploying underperforming models, introducing unexpected behaviors, and investing in AI solutions that fail to deliver measurable value.
The Evaluating LLM and Agentic Workflows Blueprint combines Cloudera AI with open-source evaluation and observability capabilities to help organizations systematically assess AI models and agentic applications before deployment. By comparing model performance, measuring accuracy and safety, and examining how agents reach their results, teams can make evidence-based decisions about which AI solutions best meet their business needs. This approach helps accelerate AI adoption, improve application reliability, and reduce the risks and costs associated with deploying untested AI systems.
Business Value:
Accelerate enterprise AI adoption with standardized model and agent evaluations on Cloudera AI, reducing testing costs, minimizing deployment risks, and improving application reliability through measurable performance benchmarks, transparent results, and repeatable AI quality assessments.
Cost Savings - Reduce AI development and testing costs through automated, repeatable model and agent evaluations; Improve engineering productivity by accelerating model comparisons and troubleshooting; Lower AI evaluation platform costs through integrated open-source tooling deployed on Cloudera; Optimize AI inference spending by identifying cost-effective models that meet business-specific performance requirements
Cost Avoidance - Prevent costly AI deployment failures by identifying inaccurate, unreliable, or unsafe model behavior before production; Minimize reputational and operational risks through standardized AI safety and performance assessments; Reduce compliance and audit risks by maintaining traceable evaluation results and reproducible testing processes; Avoid unnecessary infrastructure investments by validating model performance and suitability before adoption
Revenue Growth - Accelerate time to market for AI-powered applications through faster model validation and deployment readiness; Increase the success rate of enterprise AI initiatives by selecting models aligned with business requirements; Improve customer confidence through more reliable and consistently evaluated AI experiences; Enable faster adoption of new AI capabilities by reducing the time required to assess and introduce new models and agentic workflows
Demo
This demo shows how organizations can use Evaluating LLM and Agentic Workflows on Cloudera AI to measure, compare, and improve the performance of AI models and agents.
See how teams can select an AI model or deployed agent, choose from predefined evaluation scenarios or provide their own business-specific test data, and assess performance across criteria such as accuracy, reliability, safety, and task completion.
The demonstration highlights how evaluation results are organized into interactive dashboards, allowing users to compare different models, investigate individual responses, and understand where an AI system succeeds or falls short. By providing measurable evidence and repeatable testing workflows, the Blueprint helps organizations select appropriate AI models, identify problems earlier, and make more informed decisions before deploying AI into production. Watch the demo
Key Features
Comprehensive AI Model Evaluation: Assess the accuracy, reliability, and effectiveness of AI models against standardized benchmarks and business-specific requirements.
Agentic Workflow Testing: Evaluate deployed AI agents to determine whether they complete intended tasks, use available tools appropriately, and produce reliable results.
AI Safety and Trustworthiness Assessment: Test AI responses for factual accuracy, unsafe behavior, inappropriate content, and susceptibility to adversarial prompts.
Side-by-Side Model Comparisons: Compare multiple AI models using consistent evaluation criteria to identify the best fit for different business applications.
Transparent AI Performance Insights: Explore detailed evaluation results and interaction histories to understand how models and agents arrive at their outputs and identify areas for improvement.
Custom Business Evaluations: Create or upload organization-specific test scenarios and define evaluation criteria that reflect real-world business requirements.
Repeatable Performance Testing: Reuse evaluation datasets and track results across model versions to identify performance changes and support continuous improvement.
Private, Open-Source Evaluation: Run the evaluation platform within Cloudera AI using open-source tooling, providing greater control over sensitive test data and reducing dependence on external evaluation services.
Use Case
Organizations deploying generative AI and autonomous agents face growing challenges determining which models are best suited for their business needs, validating application reliability, and ensuring AI systems behave consistently before entering production. Traditional testing approaches often lack standardized evaluation criteria, making it difficult to compare models, identify performance issues, or demonstrate readiness to business stakeholders. The Evaluating LLM and Agentic Workflows Blueprint addresses these challenges by providing a unified evaluation platform on Cloudera AI that measures model accuracy, agent task completion, safety, and overall performance through repeatable tests and transparent results. By replacing subjective AI assessments with measurable evidence, organizations can accelerate model selection, improve AI application quality, reduce deployment risks, and confidently scale AI initiatives across the enterprise.
Architecture
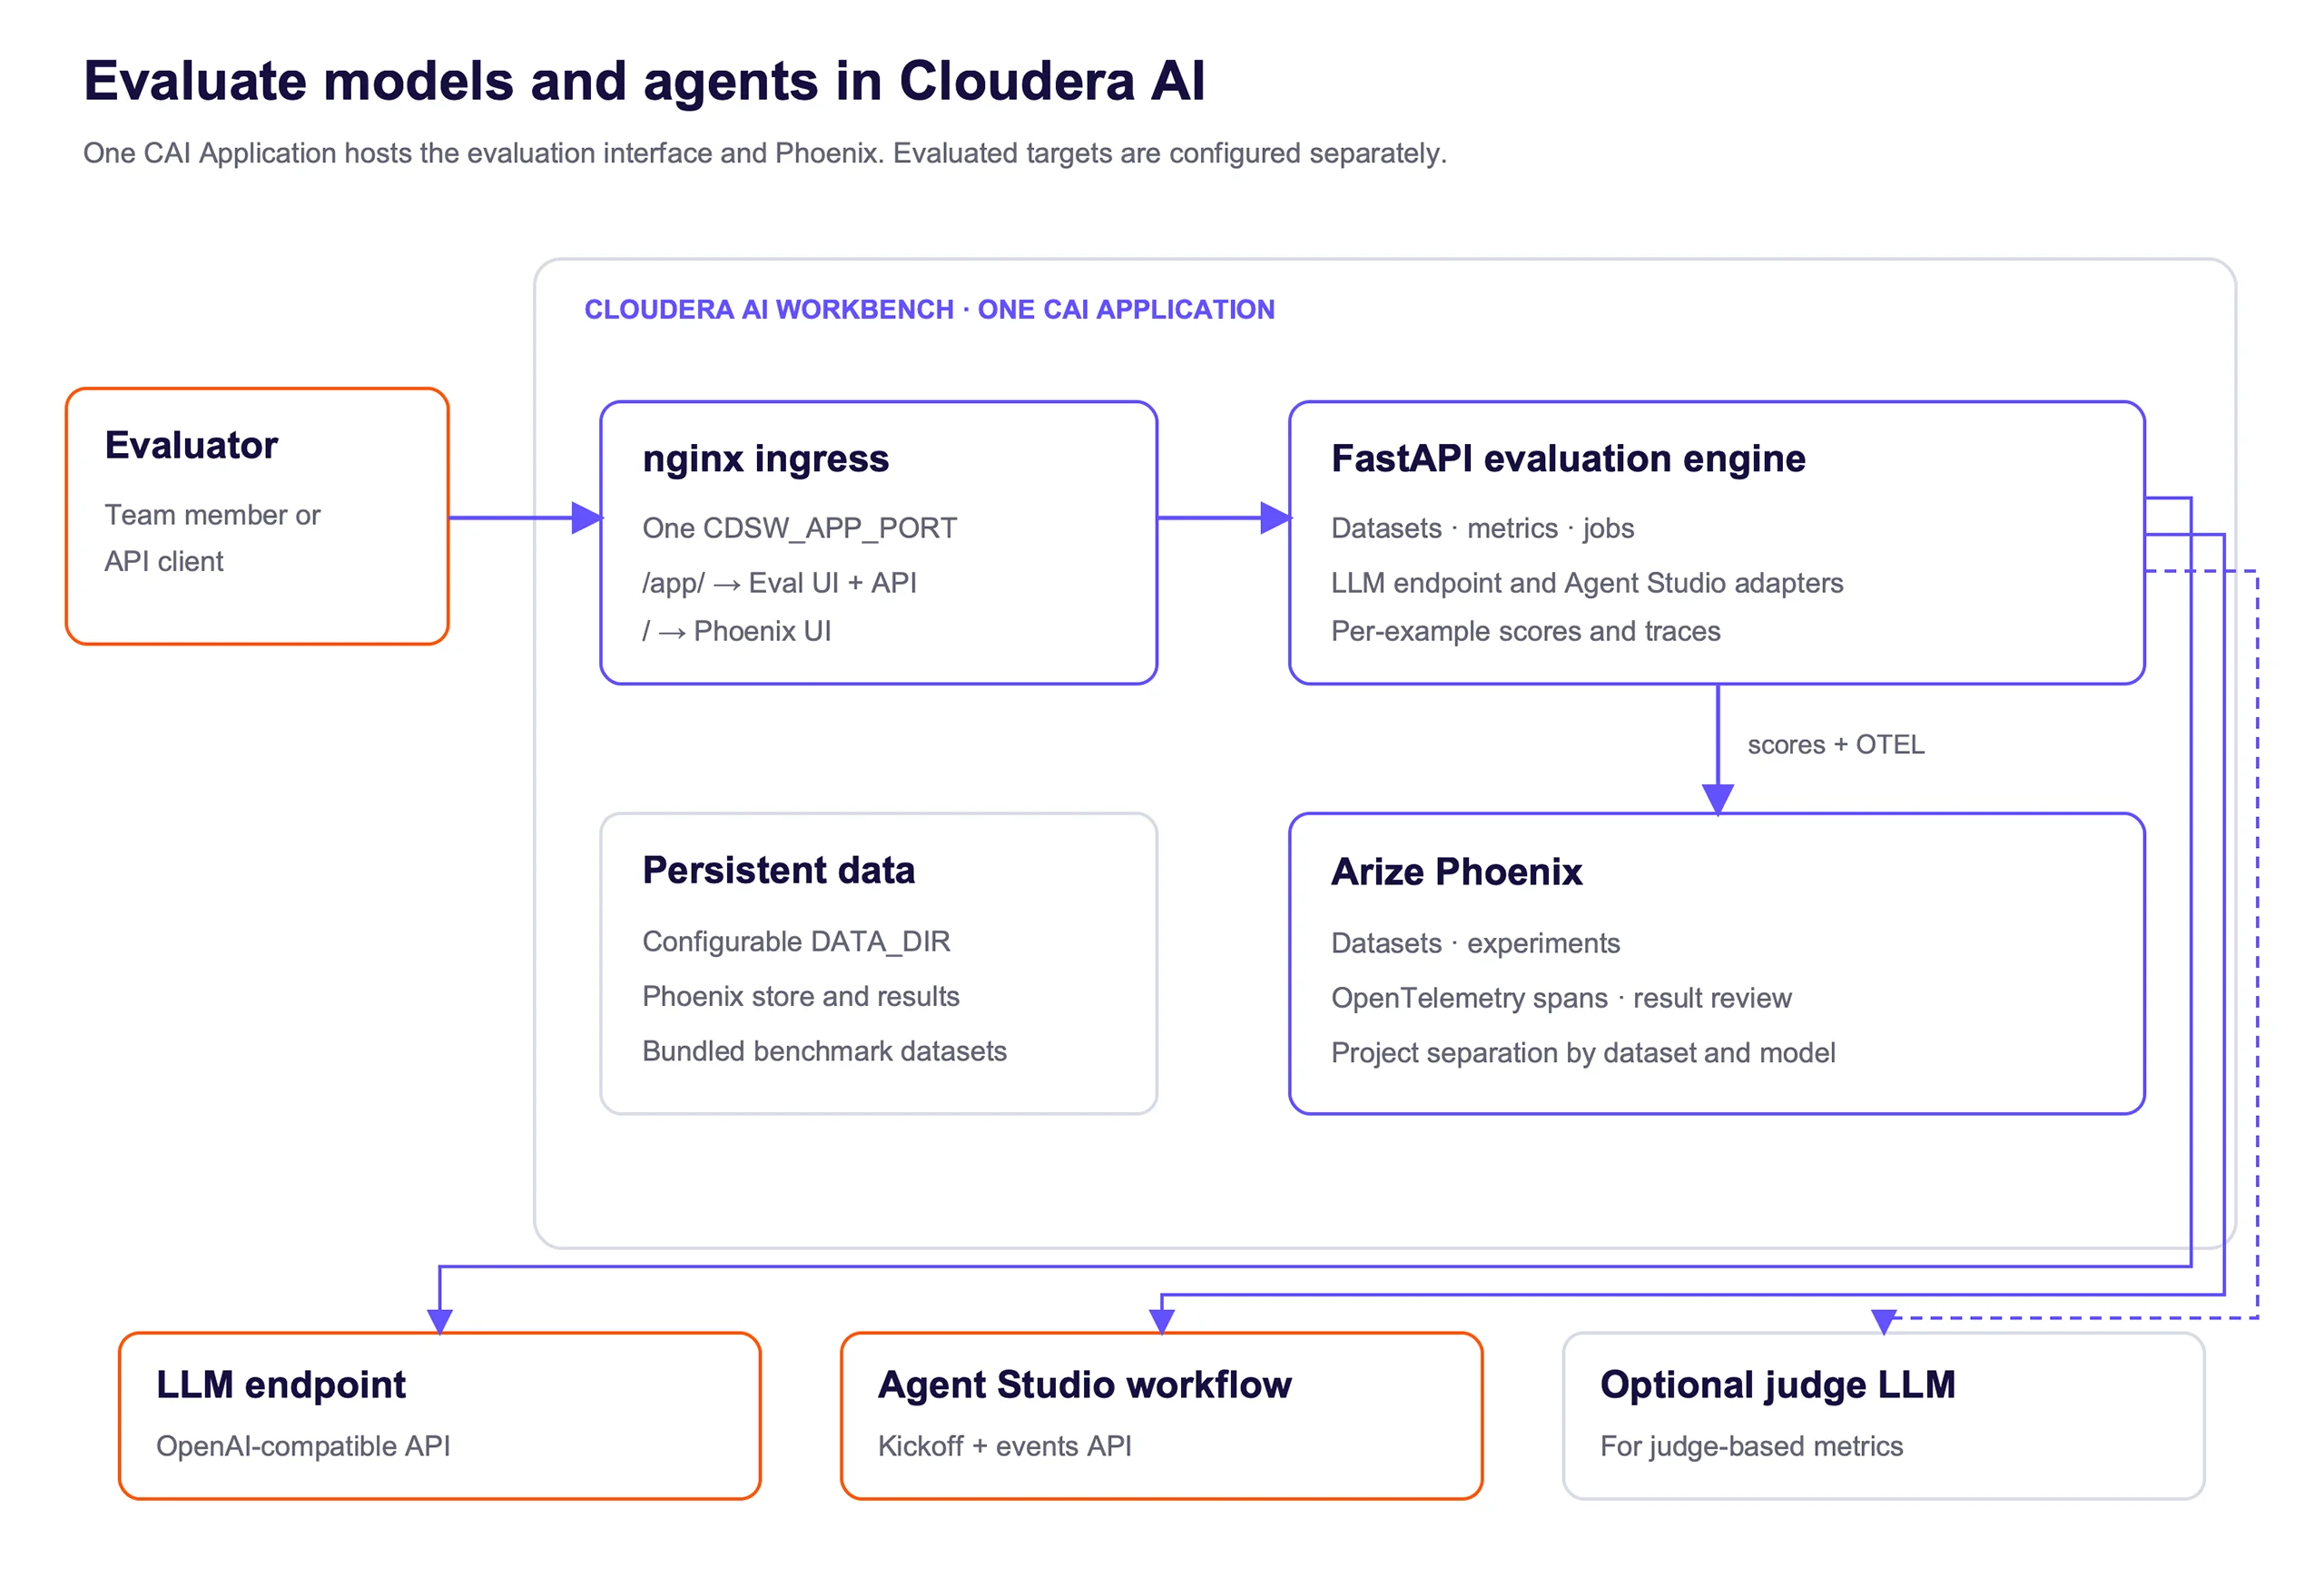
The platform ships as a single CAI Application where an nginx reverse proxy routes web requests to Arize Phoenix and the FastAPI eval engine. The engine loads datasets, invokes the target LLM endpoint or Agent Studio workflow, computes metrics, and records traces and experiments directly into Phoenix.
Evaluations generate spans per example and store runs in isolated Phoenix projects for seamless side-by-side comparison. The Application supports flexible deployment options, including CAI AMP, CI/CD pipelines, Docker, and CAII Applications.
Your form submission has failed.
This may have been caused by one of the following:
- Your request timed out
- A plugin/browser extension blocked the submission. If you have an ad blocking plugin please disable it and close this message to reload the page.